Sir Lucian Grainge Is Right About Artist-Centric Streaming. Let’s Take the Next Step.

When Universal Music Group CEO Sir Lucian Grainge says that successful artists should be compensated for the value they bring to streaming platforms, I agree with him.  In fact, I think his argument points toward an even more fundamental reconsideration of the economics of music streaming that could get to the same end state.

During Universal Music Group’s October 29, 2026 earnings discussion, Mr. Grainge and UMG Chief Digital Officer Michael Nash raised important questions about how streaming services value music, particularly as platforms confront increasing volumes of AI-generated recordings. The underlying issue is whether a system that allocates royalties principally according to streaming volume adequately recognizes the contribution of artists who develop careers, build audiences, and attract paying subscribers.

That is a legitimate question, and Mr. Grainge is right to raise it. I would extend his argument one step further: rather than simply determining which artists deserve a larger share of an existing royalty pool, why not restore the ability of artists to negotiate the actual price of their music on a per-stream basis and forget the pool ideal altogether? And why not at least give them the freedom to withhold their recordings when a streaming service doesn’t want to pay that price?

The Problem With a Fixed Royalty Pool

The revenue-sharing model may have been understandable when subscription services were getting started. Streaming companies faced uncertain subscriber demand, competition from piracy, and substantial technological investment. Record companies wanted digital distribution to succeed.  A fixed revenue share model offered a way to participate in its growth without imposing both potentially unlimited royalty liabilities and higher transaction costs from negotiation with individual artists.

But that was twenty years ago. Spotify’s third-quarter 2026 financial results reported 306 million premium subscribers, approximately €5 billion in quarterly revenue, and €672 million in quarterly operating income. We are no longer dealing with a struggling startup.  Another way we know that is that Spotify co-founder Daniel Ek cashed out and is now going for the real money just like Google’s Eric Schmidt—blood money from AI drones and arms dealing.

Yet streaming still treats music royalties largely as an allocation of a negotiated percentage of service revenue. If a service has $100 available for royalty distributions, giving one artist an additional $10 generally means allocating $10 less to someone else—unless the service increases the amount available. This is the zero-sum problem of the Big Pool that is the only price discovery model in the world that treats all artists as of equal value.

It is not an unavoidable characteristic of music licensing. It is a consequence of the business model the parties chose. Ironically, the labels chose that model to help a startup that then turned around and bit them.  The zero-sum problem becomes particularly acute when we try appropriately to recognize successful artists through preferential weights. Some artists contribute more economic value to a platform than others. Mr. Grainge is right about that. But why should their reward necessarily come from the relative shares of other artists which I doubt that he also wants?

Instead of saying, ‘Please give me a larger share of your royalty budget,’ an artist should be able to say, “Here is the price of my recording. If you don’t want to pay it, don’t play it.” That moves us from the Oliver Twist model of asking for a little more toward a genuine and orderly marketplace based on choice.  Real democracy rather than the faux competition of the fixed pool determined by our tech overlords.

Free Agency Means the Freedom to Negotiate

In 1999, I wrote Why Free Agency Matters: The Coming Changes in Record Company Artist Relations. The paper examined how digital technology could change the relationship between recording artists and the businesses that distribute and commercialize their music. Technology could give artists greater freedom to select partners, negotiate terms, and choose how recordings reach listeners.

That did not mean record companies would become irrelevant. A successful and focused label can provide extraordinary value through financing, marketing, promotion, distribution, and career development. But I did mean that artists should have meaningful choices.

Twenty-seven years later, we have remarkably efficient global distribution but an increasingly concentrated practical relationship between musicians and the platforms that reach listeners, especially Spotify. An artist may have more ways to distribute recordings than ever before, yet less commercial leverage over the terms on which those recordings are consumed, at least on streaming platforms.

Spotify is so important to music distribution that artists and labels may feel unable to withhold recordings even when they believe a share of the Big Pool is inadequate. The ability to bargain is inseparable from the ability to decline an offer. Free agency ought to include freedom to choose when, where, and at what price a recording is available.

Two Royalty Systems Can Coexist

Consider two potentially available licensing paths. The first would be individually negotiated per-use licensing. An artist or label could negotiate a penny rate for qualifying streams, backed by terms that already exist today in streaming licenses—minimum guarantees, appropriate accounting, audit rights, and other commercial protections. The rate would reflect the recording’s value, the artist’s audience, competitive alternatives, and the parties’ willingness to make a deal.

This should not be reserved for major-label superstars. Independent artists and labels should have the same contractual freedom, even if their rates and bargaining leverage differ. An artist with low streams might begin their career in a collectivist Big Pool system and later negotiate directly after developing a commercially significant audience—a natural form of upstreaming, rather than an arbitrary algorithmic cutoff like the Discovery Mode free goods approach.

The second path would preserve collective royalty accounting for artists who prefer it. There are millions of recordings generating low to modest revenues, partly as a function of the Big Pool model.  Separate negotiations for every track would be impractical. Pool accounting can provide administrative efficiency. Nothing about the proposal requires eliminating it.

But the systems must be separated correctly. Recordings on individually negotiated rates should not be counted in the Big Pool. Payments under those direct licenses must not simply be deducted from the royalties otherwise available to remaining pool participants. Otherwise smaller artists would subsidize the higher negotiated compensation due to the zero-sum problem.  If one artist gets more, that reduces the per-stream rate for everyone else.

The pool for streams not covered by direct licences therefore requires its own defined and protected funding obligation, transparent calculations, and audit rights. Establishing that funding baseline is a substantive commercial negotiation, not simply a matter of excluding directly licensed streams from the denominator. The systems needed to administer both payment models already exist; the real challenges are economic and contractual.

The Ethical Pool: Artist Choice Within Collective Accounting

In 2018 I published Arithmetic on the Internet: The Ethical Pool Solution to Streaming Royalty Allocation. That proposal addressed a different, related question: who receives money inside a collective pool? It did not propose abandoning revenue sharing altogether.  But that was almost ten years ago, and we have moved on to bigger problems that were predictable, but largely unaddressed until now.

Under conventional “streamshare” accounting, a subscriber’s royalty contribution is not necessarily directed only to the artists that subscriber listens to. My Ethical Pool (sometimes called “artist centric”) proposed that listeners could elect to direct their eligible royalty contribution to participating artists they actually played, while artists could choose whether to participate. The Ethical Pool and the conventional Big Pool would coexist.

That proposal concerned allocation, not the independently negotiated price of a use. A penny-rate system addresses the latter question. The two ideas are complementary: artists who prefer collective accounting could remain in a pool, possibly one offering an Ethical Pool option, while artists seeking their own per-use terms could pursue them. The connecting principle is choice.

AI Makes the Revenue-Pool Question More Urgent

Generative AI sharpens the problem with the royalty cap. Lucian Grainge has questioned what streaming-volume market share means when AI-generated tracks and recordings by working artists compete for listening. It is important to distinguish fraudulent streams, unauthorized uses of protected recordings or identities, and lawful listening to AI-generated music. Those raise different legal and economic questions. Given the abject failure of distributors and DSPs to deal with AI slop (see the University of Chicago study the Artist Rights Institute quoted in our comment to the Copyright Office’s consultation on streaming fraud), the royalty cap is in sharp focus today.

Spotify has said it excludes detected artificial streams from royalty calculations and maintains eligibility rules for certain recording payments. We should not assume that every AI track automatically earns royalties or that every questionable play dilutes the pool. Still, when eligible listening shifts toward new content without a proportionate increase in the revenue cap, all other recordings may receive smaller relative shares anyway.  This is where we came in.

A negotiated penny rate would not eliminate AI competition or solve questions of copyright, consent, or rights of publicity. It would, however, separate the contractual compensation for a qualifying use from the changing volume of other eligible recordings competing for the same pool. That is one reason the structural distinction matters.  (ARI argues that it would also put the economic incentive in the right place to combat AI slop and streaming fraud.)

Discovery Mode and the Cost of Algorithmic Dependence

Spotify’s Discovery Mode illustrates another aspect of the industry’s dependence on platform-controlled distribution. Eligible recordings can receive consideration in certain personalized recommendation contexts in exchange for a commission on the associated recording royalties.

Participation is optional, and an artist may reasonably believe the promotional opportunity is worth the cost. Nevertheless, the arrangement illustrates the imbalance created when a platform controls a significant part of discovery while also controlling the mechanics of royalty allocation. Too many artists spend time trying to please an algorithm rather than making and selling recordings. There are only so many hours in a day.

That is not, standing alone, proof of unlawful conduct. It is a reason to make sure artists have genuine commercial alternatives.

The Market Is Already Experimenting With Windowing

We need not speculate about whether artists would experiment with delaying streaming if they had greater freedom. Some already do. NxWorries released Why Lawd? on vinyl, CD, and cassette in June 2024 one week before making it available on streaming services. Jack White distributed physical copies of No Name before a wider digital release. Independent labels, including International Anthem, have experimented with physical and download sales before streaming availability.

In 2026 Sturgill Simpson, recording as Johnny Blue Skies, released Mutiny After Midnight on physical formats without an initial streaming or download release. Its reported chart performance showed that significant demand can be captured without immediate inclusion in the streaming catalog.

We do not know that these artists were intentionally trying to avoid release-parity obligations under streaming distribution agreements. There are excellent commercial reasons to sell physical recordings or downloads before streaming. But the practical effect can be similar: the artist establishes a window in which fans purchase the recording before it enters the streaming royalty system, without necessarily favoring one streaming service over another.

Bandcamp supports direct sales of recordings, downloads, and physical merchandise; Patreon supports memberships and early access. Neither platform proves that delaying streaming is always profitable. Both demonstrate that artists and fans value business relationships outside the pooled-subscription model. A $25 record sale is not equivalent to a $25 artist profit, but it is a direct transaction tied to a particular recording rather than a fractional claim on a service-wide royalty allocation.

The lesson is not that every artist should abandon streaming or return to CDs. It is that immediate streaming availability should be a commercial choice, not an unavoidable contractual condition of releasing music. The industry is already experimenting with release sequencing, sometimes through a cumbersome route. It should be possible to negotiate comparable flexibility directly in streaming licenses.

Bring Back Digital Windowing

There are prominent precedents. Taylor Swift initially withheld Red from Spotify in 2012, withheld 1989 in 2014, and removed her existing catalog. Adele’s 25, released in November 2015, was not available on major on-demand streaming services at launch and only reached them in June 2016. Those episodes do not prove that withholding is optimal for every artist. They establish that the choice can have commercial significance—just look to the bleating from Daniel Ek in mansplaining to Taylor and Adele why the earth was actually flat.

Suppose an artist proposes a negotiated penny rate for a new album and Spotify declines. Why shouldn’t the artist be able to license a limited exclusive window to Apple Music, Tidal, Deezer, or another willing distributor—or sell first through direct-to-fan channels—while leaving older catalog on Spotify? The artist could take a short-term risk in exchange for a better offer. A competitor could pay for valuable differentiation.

Some historical digital licensing arrangements have included broad availability, simultaneous-release, or parity commitments. But to the extent such terms prevent an artist or label from testing competing offers, they deserve reconsideration. Without the ability to withhold a new recording, the threat to walk away may be largely illusory.  (Because what Spotify really wants is a compulsory license, so they are trying to contract their way to that end.)

A Competition Question Worth Asking

The contractual issue also raises a legitimate, fact-dependent antitrust question. A broad delivery obligation may have been commercially defensible while streaming services were struggling to establish viable catalogs. Its competitive consequences may be different in a mature market dominated in practical terms by a few large platforms.

A service’s scale or profitability alone does not prove monopoly power. Nor does every availability requirement violate antitrust law. Any analysis would need the actual contract language, a properly defined market, evidence of market power, the degree and duration of competitive foreclosure, and consideration of legitimate business justifications.

Still, a facially nonexclusive license may constrain competition if its accompanying terms deprive rival distributors of meaningful opportunities to bid for exclusive releases. That is a question worth investigating.

There is also a critical distinction between a label independently declining Spotify’s proposed terms and competing labels collectively agreeing to withhold music. The former is generally ordinary licensing discretion; the latter can create antitrust risks. The goal is independent competition for music rights, not a coordinated boycott.

Completing the Artist-Centric Argument

I think Lucian Grainge has opened the correct conversation. Successful artists create substantial value for streaming platforms, and the economics should recognize it. I would extend that principle by restoring contractual freedom rather than relying solely on a different distribution formula within the same fixed pool.

Allow artists to negotiate their own penny rates directly with streaming services. Spotify is the obstacle: it refuses to negotiate individual royalty rates or contract directly with artists, regardless of the price they might offer. Instead, Spotify requires them to use intermediary distributors, including its preferred distributor DistroKid, in which Spotify acquired an ownership interest. Artists should be free to negotiate independently, remain in the Big Pool if they choose, and explore more ethical, listener-directed royalty allocation. They should also be free to withhold or window new recordings when a streaming service refuses their terms—a big pool might be acceptable for back catalog but not for new releases.

These changes would not guarantee higher income for everyone. But they could encourage services to compete for valuable releases, give artists a genuine price-negotiation option, and avoid making smaller artists automatically finance every premium won by larger ones.

Twenty-seven years after Why Free Agency Matters, the same principle applies. Technology should increase an artist’s commercial freedom, not reduce it. Sir Lucian Grainge is right to insist that artists be compensated for the value they create. I would extend the argument to its logical conclusion: artist-centric streaming should mean the freedom to window, negotiate price, choose distribution arrangements, and say no when the deal isn’t good enough.

That is not a rejection of streaming. It is a proposal to make streaming work more like a competitive market which it definitely is not.
Eventually You Run Out of Other People’s Content: How Google May Win the AI Race But Lose on the AI Economics

[This post originally appeared on the True Enough Substack]

The greatest threat to Google isn’t necessarily that OpenAI, Anthropic, or another competitor will defeat it in artificial intelligence. It’s that Google may successfully defend its market position while destroying the extraordinary economics that made its search monopoly so valuable in the first place.

For more than two decades, Google operated one of the most capital-efficient businesses in corporate history. It organized other people’s work product, attracted consumers searching for those brands, sold advertising against their intentions, and generated enormous amounts of free cash flow.

Thanks in significant part to statutory safe harbors that hurt everyone but Google, the underlying content was largely somebody else’s expense. Publishers wrote the articles. Universities funded the research. Songwriters wrote and musicians recorded the songs financed by record companies and music publishers. Businesses produced technical documentation. Google indexed that material and monetized the process of finding it.

Google certainly spent substantial sums developing its search infrastructure, but it didn’t have to bear the cost of creating most of the content that made Search useful. And once the infrastructure and advertising marketplace were established, incremental revenue could be generated at relatively low incremental cost.

Artificial intelligence threatens to reverse that equation.

Instead of directing consumers to content somebody else financed and created, Google is increasingly using expensive computing infrastructure to generate answers itself (scraping content somebody else financed and created). The underlying information may still come from other people’s work, but Google now incurs the computational expense of manufacturing the answer.

That requires significant capital expenditure on data centers, specialized processors, electricity, cooling, memory, model development, and continuous reinvestment in rapidly evolving technology. And that means Google is transitioning from a relatively low-capital-expenditure, high-moat business to a high-capital-expenditure business with potentially weaker competitive advantages.

And its latest financial statements reveal just how expensive that transition has become.

The $53.5 Billion Free-Cash-Flow Collapse

The most revealing number in Alphabet’s third-quarter 2026 financial results isn’t revenue, earnings per share, or even capital expenditures. It’s free cash flow.

During the first nine months of 2025, Alphabet generated approximately $112.3 billion in operating cash flow and spent $63.6 billion on capital expenditures. That left approximately $48.7 billion in free cash flow. During the corresponding period in 2026, operating cash flow actually increased to $127.1 billion.

But capital expenditures more than doubled to approximately $132 billion. The result was negative free cash flow of approximately $4.8 billion.

Think about that.

Alphabet’s operating cash generation improved by nearly $15 billion, yet its free cash flow deteriorated by approximately $53.5 billion. The company’s cash-generating engine was performing better. But the cost of financing its future was consuming more cash than that engine produced.

The quarterly progression is particularly revealing. Alphabet generated positive $10.1 billion in free cash flow in the first quarter of 2026, followed by negative $5.9 billion in the second quarter and negative $9.1 billion in the third.

To be clear, these are Alphabet-wide figures, not just AI. The capital expenditures support Google Cloud and other activities as well as Search, and investments made today may produce substantial future revenue. But that qualification doesn’t eliminate the economic issue. I think it sharpens it quite a bit.

The fundamental question is no longer how much revenue Google can generate. It’s how much capital Google must continually invest to generate that revenue—and how much cash remains for shareholders afterward. Old Google expanded by reinvesting a portion of its extraordinary cash flow. New Google is increasingly consuming that cash flow to build the infrastructure necessary to remain competitive.

That’s not merely a change in spending priorities. It may be a fundamental change in the quality of the business.

The Equity Offering That Changed the Story

In June 2026, Alphabet raised approximately $49.6 billion in net proceeds through a combination of common and mandatory convertible preferred stock, including a private placement with Berkshire Hathaway.

Alphabet expressly identified investments in AI infrastructure and computing capacity among the purposes of the financing. That’s kind of a man bites dog story.

It also established a $40 billion at-the-market equity issuance program, selling another $12.4 billion of common stock during the third quarter. The stated primary purpose of that ATM program was to meet tax obligations associated with employee equity grants, rather than directly finance AI infrastructure.

Meanwhile, Alphabet continued issuing substantial amounts of debt.

The June financing is especially significant because Google historically generated enough cash to finance its expansion internally while repurchasing billions of dollars of its own shares not issuing new shares to finance capex. Now the company has turned to outside capital to supplement that cash generation during its AI infrastructure expansion.

This does not establish that Alphabet was running out of money. It has enormous resources, and raising capital when financing is available on attractive terms may be perfectly rational.

But the reversal is striking.

Google historically generated extraordinary free cash flow without paying dividends, instead returning capital primarily through share repurchases. Now the economics of AI are forcing a reassessment of how much of that cash the company can retain, reinvest, or return to shareholders. That changes the shareholder proposition.

Capital-intensive growth financed partly through new equity must produce sufficient incremental returns not only to justify the investment but also to offset the dilution of existing shareholders.

And a business that repeatedly needs large new investments to maintain its competitive position is economically different from one whose existing infrastructure can support substantial growth with comparatively modest incremental capital.

The critical issue isn’t solvency. It’s whether Alphabet’s legendary ability to convert revenue into cash is becoming a casualty of the AI arms race.

Google Used to Monetize Other People’s Work. Now It Must Manufacture Answers.

Traditional Google Search benefited from an almost ideal division of labor. Google organized access to other people’s work product. That arrangement allowed Google to capture extraordinary value from work it did not itself finance.

A newspaper might spend thousands of dollars investigating a story. Google could index the resulting article and sell advertising to users searching for the subject. An academic might spend years developing specialized expertise. Google could organize access to the resulting research. The creator absorbed the cost of producing the underlying information. Google monetized “discovery.”

AI search changes the relationship. When Gemini generates a detailed answer, Google must supply the computing capacity necessary to produce that response. More sophisticated reasoning and increasingly complex multimodal interactions can require substantially more resources than retrieving and ranking search results.

And Google must make those investments repeatedly as competing AI systems improve. Of course, Google isn’t literally creating all the information contained in its AI answers. Much of that information still originates in third-party content that Google scrapes. Google also has long operated content-intensive businesses, notably YouTube relying on the safe harbors in Section 230 and the DMCA (which is why they push for text and data mining exceptions and why they are litigating over fair use).

But AI search makes Google more directly responsible for producing the answer presented to the consumer, rather than simply organizing access to an answer located elsewhere. That is a crucial distinction and plays directly into the economics.

Google once monetized content it didn’t have to create. Now it must pay to generate answers based substantially on content it still didn’t create.

There’s also a long-term complication. If AI-generated answers reduce visits to the publishers and other creators who supply the underlying information, the economics supporting the creation of that information may deteriorate. Google could end up weakening the very content ecosystem on which both its traditional search engine and its AI systems depend.

The Difference Between Capital Expenditure and Capital Formation

There is another distinction investors should keep in mind. Spending $200 billion on infrastructure does not necessarily create $200 billion in durable economic value. Alphabet expects capital expenditures of approximately $195 billion to $205 billion in 2026, with further substantial increases anticipated in 2027. Some of this spending will produce assets capable of generating revenue for years. But AI infrastructure is not equivalent to a long-lived monopoly franchise like Google’s.

Processors become obsolete. Models improve. Competing systems become more efficient. Hardware must be replaced. Customers may migrate toward cheaper or better-performing alternatives. And today’s enormous investment doesn’t necessarily prevent competitors from making tomorrow’s enormous investment.

That raises the possibility that some portion of AI capital expenditures will become a continuing competitive obligation rather than a one-time investment in growth.

Alphabet’s depreciation on property and equipment already increased from approximately $15.1 billion to $22 billion during the first nine months of 2026. As additional data centers and computing equipment enter service, depreciation and operating costs will continue to flow through future income statements. The cash goes out first. The accounting expense follows.

The investor’s question should be straightforward:

What return will Google earn on its next dollar invested in AI compared with the return it earned on its last dollar invested in traditional Search?

If that incremental return declines substantially, Google can grow revenue and expand its technological capabilities while becoming a less valuable business on a return-on-capital basis.

That is the real risk.

Search Revenue Is Slowing as the Cost of Defending It Accelerates

Back to Google’s earnings, Google Search revenue growth slowed from approximately 19% in the first quarter of 2026 to 17% in the second quarter and 12% in the third. Search remains enormously profitable. Indeed, Google reported strong query growth, suggesting that demand for its search services is not disappearing. But the divergence between rising engagement, decelerating revenue growth, and rapidly increasing infrastructure investment deserves attention.

AI may be expanding the number of queries while changing the economics of monetizing them. Traditional Search benefits from a mature advertising auction that converts commercial intent into revenue. AI search introduces a different consumer experience, in which users increasingly receive synthesized answers rather than navigating a series of links and sponsored results.

Google is developing advertising formats for AI, and those products may ultimately be successful. But the revenue model remains less established than the traditional search auction. And the cost per interaction may be higher.

The danger is that Google could retain users while generating less economic value from serving them. Even if AI search eventually produces comparable advertising revenue per query, it may require substantially more computing expenditure.

That is the cannibalization problem: Google’s innovation may preserve its market share while reducing the cash generation associated with that market share.

A Weaker Moat at a Much Higher Price

Google’s traditional Search moat consisted of several mutually reinforcing advantages: consumer habits, default distribution, search quality, advertiser relationships, scale, and its dominant advertising marketplace.

A competitor couldn’t simply build a good search engine. It had to recreate the commercial ecosystem. AI changes that dynamic.

Consumers can now obtain useful AI answers from Gemini, ChatGPT, Claude, Perplexity, and other AI systems. The products are not identical, and Google retains important advantages in distribution, infrastructure, proprietary chips, data, and advertising.

But conversational AI makes the basic information-retrieval experience more substitutable. The competitive struggle increasingly centers on model quality, speed, cost, and capabilities—areas where rivals can improve rapidly and technological leadership may be temporary.

This doesn’t mean AI has no barriers to entry. Frontier-model development and large-scale inference require enormous resources. But an expensive barrier to entry is not necessarily a profitable moat.

If every major competitor must continually spend billions to maintain technological parity, the result may be an exceptionally capital-intensive industry without the pricing power necessary to justify those investments.

The distinction is between spending capital to establish a durable competitive advantage and spending capital simply to remain in the game. Google’s historical Search business did the former extraordinarily well. AI threatens to make the latter a permanent condition of competition.

The Strongest Counterargument: Google Cloud

There is an obvious counterargument. Alphabet’s AI investments aren’t limited to defending Search. Google Cloud revenue increased 103% in the third quarter of 2026 to approximately $30.7 billion. Alphabet can monetize computing infrastructure through enterprise customers, AI services, subscriptions, and sales of its proprietary TPU systems.

A substantial part of the capital expansion may therefore support genuinely new revenue rather than simply replace existing Search capabilities. That’s a significant counter, and any serious financial analysis must account for it.

Google may ultimately achieve attractive returns on its AI investments across several different businesses. But investors should not assume that rapid Cloud revenue growth establishes that the capital expenditure is earning adequate returns.

Revenue growth is not return on invested capital. The question is whether the combined additional profits from Cloud, AI subscriptions, and AI-enhanced Search will justify the enormous incremental capital committed to obtaining them.

Alphabet management says it expects attractive returns on invested capital above its cost of capital and that aspiration may be realized. But in the meantime, the sharp decline in free cash flow is real, the equity financing is real, and the depreciation burden from new infrastructure is growing.

The financial statements show the cost of the bet. They have not yet demonstrated its ultimate return.

Winning the AI Race May Be the Wrong Goal

Investors are understandably fascinated by whether Gemini can outperform ChatGPT or Claude. This is the normal board room chatter. But those comparisons may distract from the more fundamental economics.

A company can develop excellent technology, maintain its market position, increase revenue, and still deliver disappointing shareholder returns if achieving those results requires too much capital. That’s the real danger Alphabet faces.

Google’s original Search franchise generated extraordinary returns because the underlying business required comparatively little incremental investment relative to the revenue and cash it produced.

The transition to AI is dramatically increasing capital requirements while potentially weakening the competitive barriers that supported those returns.

The first nine months of 2026 illustrate the transformation: operating cash flow increased by nearly $15 billion while free cash flow declined by approximately $53.5 billion.

Alphabet supplemented that cash generation with major equity and debt financing. And management anticipates that capital spending will rise further. That means The stakes are much larger than quarterly earnings or market share.

Google may be exchanging a business that generated extraordinary returns on relatively modest incremental capital for one that requires extraordinary amounts of capital merely to remain competitive.

Conclusion: The Economics Matter More Than the Technology

Google doesn’t have to lose the AI race to lose the economic advantages of its original business. It might remain a leader in artificial intelligence, preserve its enormous customer base, build outstanding products, and continue generating substantial revenue.

And yet shareholders could find themselves owning a company that requires vastly more capital to produce each incremental dollar of free cash flow. That would represent a fundamental deterioration in the quality of Google’s business, even if its technological position remained strong.

The old Google monetized other people’s work through an extraordinarily efficient discovery and advertising system. The new Google is spending hundreds of billions to build the computational machinery necessary to generate answers, defend its distribution advantages, and compete against other well-funded technology companies doing essentially the same thing.

That may be an impressive technological achievement, but the measure of its economic success won’t be how many answers Gemini produces, how large Google’s models become, or whether Google wins the latest AI benchmark.

It will be how much free cash flow remains after paying for the infrastructure required to produce those answers.

Google’s greatest AI risk isn’t losing the race. It’s winning the race and discovering that the victory has destroyed the economics that made Search one of the greatest businesses ever created.

For further reading: Alphabet, Form 10-Q for quarter ended September 30, 2026, Alphabet, Q3 2026 earnings release, and Alphabet, Q2 2026 earnings release.

The AI Bubble Is Much Worse Than They Think: Remembering the Last War

The trouble with calling speculative bubbles a feature of capitalism is that everyone remembers the survivors. Nobody remembers how bad the last war really was.

I’m a fan of Ed Dowd and read him pretty regularly. He makes an interesting argument in his recent Substack essay, “Investment Bubbles Are a Feature of Capitalism, Not a Bug“. His proposition is familiar: speculative booms finance infrastructure that survives the inevitable financial collapse. Railroads, electrical grids, and dot-bomb era fiber-optic networks were all overbuilt during speculative manias. Investors lost fortunes, companies went bankrupt, but society eventually benefited from the infrastructure left behind.

There is considerable historical truth to this argument. Unfortunately, I think it substantially understates the problem with the artificial intelligence bubble. Not because Dowd is wrong about speculative finance, but because this time the consequences may extend far beyond the investors who made the bets.

I say that as a veteran of the dot-bomb collapse. I was there for the last war. And one thing I’ve learned is that, with the passage of time, everyone remembers the victories, the heroic survivors, and the technological progress. Very few remember how bad the war actually was. And who went to prison or should have.

It’s easy to look back at the dot-com bubble and see Amazon, Google, and the great expansion of the Internet (not to mention Salesforce, PayPal and Nvidia itself). It’s harder to remember the rabid fear of missing out, the many, many businesses that disappeared, the employees laid off, the careers interrupted, the savings wiped out, the layoffs, the bankruptcies, and the communities that experienced the collapse as something considerably less abstract than creative destruction.

The historical narrative makes the winners inevitable and the losers incidental. They weren’t incidental at the time and the only thing that seemed inevitable was the financial wipeout.

The Survivors Write the History

The comforting story about the dot-com crash is that companies built too much fiber-optic infrastructure, the telecommunications companies went broke, Socks.com was a joke, and the next generation acquired the assets at bargain prices. Everyone eventually got cheaper bandwidth, and the Internet flourished. There is truth in that story, too. But it compresses years of financial destruction into a happy ending. The market may sort itself out in the long run, but it’s also true that in the long run we’re all dead.

The NASDAQ Composite fell approximately 78% from its March 2000 peak to its October 2002 trough. Companies evaporated. Investment capital disappeared. Workers who had been told they were participating in an inevitable technological revolution discovered that inevitability did not extend to their employment or stock options. Some investors could afford to wait for the next cycle. Others could not.

Dowd doesn’t deny that destruction. In fact, he describes it. What I question is his conclusion that the surviving infrastructure demonstrates that the process was ultimately a net positive. That conclusion requires accounting for the losses as well as the gains.

The important question is not whether the Internet ultimately succeeded which I guess it did if you weren’t in the music business. The question is whether that eventual success justified every speculative investment made in its name, or excused the damage caused along the way.

I suggest that it did not. And that brings us to AI. Let’s leave aside the sector-specific existential harm. The internet came for the music business—AI is coming for musicians. But there’s a lot more to worry about this time.

This Time We’re Not Just Rolling Up Dark Fiber

Dowd’s historical analogy becomes much less reassuring when we look at the physical characteristics of the assets being created. Fiber-optic cable is relatively durable infrastructure that powers the Internet. Railroad rights-of-way can have value for generations. Electric transmission systems can support a wide variety of economic activities. But artificial intelligence data centers are something else.

Data centers depend on extraordinarily expensive computing equipment that depreciates rapidly and may become economically obsolete long before the buildings housing it deteriorate. Their cooling systems, electrical configurations, and operating requirements can be highly specialized. Their profitability depends not merely on the existence of demand for computing, but on whether that demand will support the continuing expense of providing it.

Buying a bankrupt railroad at twenty cents on the dollar is one proposition. Railroad tracks can be upgraded. Buying a bankrupt AI data center filled with yesterday’s chips, whose replacement costs may exceed the market value of the enterprise, is quite another. Some of the associated infrastructure will certainly retain value. Transmission lines, substations, and buildings may find alternative uses. But we cannot simply assume that every billion dollars invested in AI infrastructure becomes a permanent billion-dollar contribution to society.

The distinction is between infrastructure that becomes cheaper after a financial collapse and infrastructure that becomes obsolete. Those are not the same thing. I don’t see a conga line of buyers for obsolete chips.

Railroads Didn’t Destroy Aquifers

There is another problem with Dowd’s historical analogy that deserves special attention. Railroads, electrical grids, and fiber-optic networks certainly imposed environmental costs. Railroads transformed landscapes, disrupted ecosystems, and facilitated resource extraction. Electric generation produced enormous pollution. These were hardly environmentally benign enterprises.

But the infrastructure itself did not ordinarily depend on consuming vast quantities of local groundwater to remain operational. Neither did they build a private electrical generator system or behind-the-meter nuclear power. A bankrupt railroad could leave behind tracks that another operator might use. A bankrupt telecommunications company could leave behind fiber-optic cable that continued carrying traffic for years.

An AI data center, especially in a water-stressed region, presents a different proposition altogether. Its operation may depend on substantial, continuing water consumption, whether directly through cooling or indirectly through electricity generation. If that demand contributes to depletion of an aquifer, the environmental loss may persist long after the data center itself becomes obsolete and the investors have evaporated.

In many rural regions, groundwater depletion can contribute to land subsidence, soil degradation, and cascading and broader ecological damage. Where combined with drought, vegetation loss, and unsustainable land use, it may also contribute to desertification.

Not every data center consumes enormous amounts of local groundwater. Cooling technology, water sourcing, climate, and local hydrology matter. But the possibility of irreversible damage ought to be accounted for before construction, not merely acknowledged after the financing collapses. God told Noah to build the Ark before the rain.

You cannot buy a depleted aquifer out of bankruptcy at twenty cents on the dollar and assume the water will return.

And that is the fundamental accounting error in the economically rational story about infrastructure bubbles. Dowd counts the value of the railroad tracks, the generating stations, and the fiber-optic cables that survived the speculative crash. We also need to account for the natural resources consumed, the landscapes transformed, and the public liabilities left behind? The prospect of further public support if private capital retreats is not hypothetical policy territory; it is a risk worth examining before commitments become irreversible.

The comparison becomes even more troubling when the useful life of the computing equipment may be measured in years while the consequences of groundwater depletion may persist for generations. The railroad tracks survived the railroad bubble.  Will the aquifers survive the AI bubble? That is a considerably more serious question than whether investors will eventually find bargains among the wreckage.

The Land, the Water, and the Electricity Don’t Go Bankrupt

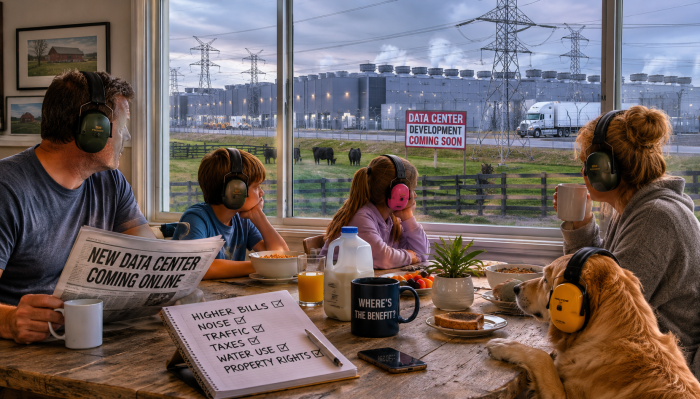
The aquifer problem illustrates a larger weakness in Dowd’s analysis. Financial capital is not the only resource being consumed. Across the country, communities are being asked to accommodate immense data-center campuses, new generating capacity, transmission corridors, substations, water infrastructure, and associated industrial development. And indirectly, for now, bear the cost of these negative externalities.

Some projects require extraordinary amounts of electricity. Others threaten to transform agricultural land, rural landscapes, and communities whose residents never imagined they would become industrial centers serving the AI economy. Much less find their family homes taken by eminent domain to build power plants, transmission lines, and substations.

The AI investors can measure their exposure in dollars and securities. The communities may measure theirs in acres, gallons, utility bills, and lost opportunities to use their land and resources for other purposes. These are different kinds of risk.

If an AI developer goes bankrupt, the investors may write down the value of the enterprise. The local aquifer does not receive a corresponding write-up. The farmland does not automatically return to agricultural production or the original family owners. The transmission corridor does not disappear. And the surrounding community does not recover the years spent fighting over its future.

Financial losses can be discharged or restructured in bankruptcy. Environmental damage and community disruption often cannot. The problem with using the history of infrastructure bubbles to rationalize today’s AI buildout is that it assumes the surviving infrastructure represents a residual benefit without fully examining what was consumed to create it.

A financial bubble can destroy financial capital. An infrastructure bubble can also destroy natural capital. One is fungible and can be replaced. One is not fungible and cannot be replaced. And unlike a distressed asset, depleted natural capital may not be available for purchase, refinancing, or reuse. Nature may not give us a second act.

The Bailout Has Already Begun

There is another feature of the AI bubble that makes the comparison to earlier infrastructure booms particularly questionable. The public is already helping finance it whether they realize it or not.

Across the country, state and local governments are granting data-center developers sales-tax exemptions, property-tax abatements, infrastructure incentives, and other subsidies. According to the National Conference of State Legislatures, 38 states offer dedicated data-center tax incentives. Many beneficiaries are among the wealthiest and best-capitalized corporations in history. These are not struggling entrepreneurs who cannot obtain financing for a promising new invention. They are companies spending extraordinary sums on infrastructure they insist is indispensable to their future profitability. And their biggest allies include the President of the United States and the World Economic Forum. These are not plucky little startups.

If the investments are so compelling, why must taxpayers subsidize them?

The answer is not self-evident. Yet the public is already surrendering tax revenue to support a speculative investment cycle whose ultimate economics remain uncertain. Call these incentives economic development if you like. From the taxpayer’s perspective, they are a subsidy today, not a hypothetical bailout tomorrow.

And that brings us to the increasingly circular character of AI financing.

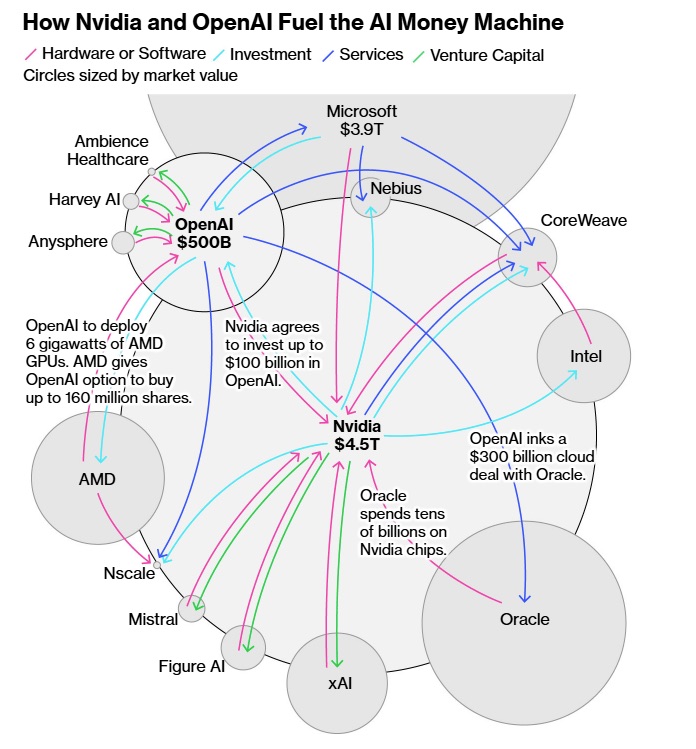
Major technology companies invest in AI developers that purchase their computing services. Chipmakers like Nvidia provide financing and guarantees for projects that buy their chips. Cloud providers commit capital to customers that commit to buying cloud capacity. Nvidia’s own securities filings disclose substantial guarantees supporting AI infrastructure leases, illustrating how suppliers, customers, and financiers can become financially interdependent. Each transaction may have a legitimate commercial explanation. Collectively, however, they raise an uncomfortable question: How much of the AI industry’s apparent demand is being financed by the same companies that benefit from supplying it? Where is the ROI?

The distinction matters because customer financing is not the same thing as independent customer demand. A company can sustain enormous spending commitments while investors remain willing to supply fresh capital. But eventually the enterprise must generate enough revenue from customers outside the financing circle to justify the investment.

What happens when the new money slows down? Not that it’s a ponzi scheme or anything.

The developers may still owe billions under computing contracts. The lenders may still hold debt secured by rapidly depreciating equipment. The utilities may already have built transmission and generating infrastructure. And the communities may already have surrendered tax revenue, groundwater, farmland, and control over their surroundings.

At that point, the “Because China” argument for further public assistance practically writes itself: these facilities are essential to national competitiveness, the electrical infrastructure has already been built, the jobs must be protected, and allowing the industry to collapse would threaten the broader economy.

That pressure from Washington DC does not conclusively establish that another TARP-style bailout is inevitable. It establishes that the circumstances in which one might be demanded are foreseeable and are already on the horizon.

The taxpayer is already subsidizing the boom. The danger is that the taxpayer will also be asked to finance the bust. And unlike the venture capitalists, the taxpayers never agreed to make the investment. And most of them wouldn’t want more AI if anyone asked.

Who Gets the Bill?

Those existing subsidies are only the first layer of public exposure. The second is the risk that utilities and governments will be left supporting infrastructure built for demand that never fully materializes. The AI buildout increasingly depends on institutions that extend well beyond the private investors making speculative bets.

Consider an electric utility that expands its transmission and generation resources to accommodate anticipated data-center demand. If the demand materializes and the customer pays its full share, the investment may be justified. But what happens if the developer disappears, the project is canceled, the promised electrical load never materializes, or technological improvements make the facility uneconomic? 

Who pays for the infrastructure? The answer depends on utility contracts, regulatory treatment, and financial guarantees. But absent adequate protections, some costs may be shifted to ordinary ratepayers. People who never invested a dime in artificial intelligence may find themselves paying for an unsuccessful artificial intelligence investment through their monthly electric bills or a taxpayer bailout.

That is not creative destruction. That is the socialization of private speculative risk. Similar questions arise with tax abatements, public infrastructure improvements, water-system expansions, and other incentives offered to attract developments promising extraordinary economic benefits. And there is a particularly troubling possibility: communities may end up paying for infrastructure that no longer has the economic purpose used to justify its construction.

A railroad might be reorganized and continue carrying freight. A transmission line built primarily to serve an anticipated AI load could become an expensive stranded asset if the demand never arrives. The investors may be gone. The ratepayers will still be there. I give you Amtrak.

The New Gold Rush Is Taking Place in Someone Else’s Backyard

One striking characteristic of the data-center expansion is the increasingly organized resistance from ordinary people. In Texas, Georgia, Virginia, and elsewhere, communities are confronting proposals that could permanently change the character of the places where they live. Their objections are not necessarily objections to technological progress. They are often objections to who gets to make the decisions, who receives the benefits, and who bears the costs. 

A developer can describe a 900-megawatt data center as an investment in the future. The people living nearby may see an enormous industrial load competing for electricity and water, accompanied by transmission lines, altered landscapes, uncertain employment benefits, and possible increases in their utility bills. Both descriptions may refer to the same project. But only one necessarily appears in the investor presentation.

There is a fundamental difference between financing speculative infrastructure with voluntary investment capital and requiring a community to absorb the environmental and economic consequences of that speculation. The residents are not venture capitalists. They did not buy shares in an AI company. They were not promised equity in exchange for the use of their groundwater, their electrical infrastructure, or their community’s future.

And they should not be treated as involuntary guarantors of the industry’s business model.

The Economics of Obsolescence

Dowd correctly identifies the threat that lower-cost AI models, increasing competition, and changes in the economics of computing pose to current investment assumptions. But this observation also undermines the conclusion he draws from the historical infrastructure cycle. As AI models become dramatically more efficient, today’s infrastructure may well prove unnecessary or uneconomic very quickly.

Certainly, cheaper computing could stimulate additional demand. That possibility should not be dismissed. But neither should the opposite possibility: technological progress may undermine the value of facilities whose investors assumed that computing requirements would continue growing along a particular trajectory. 

A railroad track laid in 1873 might remain useful in 1923. A data center designed around a particular generation of GPUs may become economically obsolete in a fraction of that time. But the data center industry tells communities that these projects are long-term investments. The industry’s own research anticipates major infrastructure renovations within the first decade and continual replacement of computing equipment. The question is not simply whether a data center becomes obsolete. It is who pays to keep it from becoming obsolete—and who bears the “stranded asset” costs if the economics stop working.

Research from Microsoft published in 2026 acknowledges that successive generations of AI hardware demand greater electrical power and more demanding cooling systems, potentially making existing data center infrastructure obsolete. Modern high-density GPU racks can produce four to eight times the heat of conventional CPU systems. (Rearchitecting the Datacenter Lifecycle for AI: A TCO-Driven Framework (https://arxiv.org/abs/2509.26534), Jovan Stojkovic, Chaojie Zhang, Íñigo Goiri, and Ricardo Bianchini, Microsoft Research, ISCA 2026, June 2026.). This is not merely a matter of replacing servers. It can require substantial reconstruction of electrical distribution, cooling systems, and physical facilities.

Industry reporting (https://www.datacenterknowledge.com/data-center-construction/ai-demands-stretch-the-limits-of-data-center-retrofits) confirms that existing data centers are already encountering these limits. Facilities designed for conventional computing may be unable to accommodate the power density, liquid cooling, and structural loads of newer AI systems without extensive renovation. Some can be economically retrofitted. Others may be unsuitable for the next generation of hardware.

And what happens when an operating data center finally closes?  An August 2026 analysis from Columbia Law School’s Sabin Center for Climate Change Law warns that abandoned hyperscale facilities may be exceptionally difficult to repurpose.(https://blogs.law.columbia.edu/climatechange/2026/08/06/decommissioning-data-centers-avoiding-stranded-assets/) Their enormous size, specialized infrastructure, electrical equipment, and environmental cleanup requirements distinguish them from ordinary commercial buildings. The analysis recommends mandatory decommissioning plans and financial assurance mechanisms, including bonds, to prevent communities from inheriting the cleanup bill. Some Pennsylvania jurisdictions have already adopted such requirements, including provisions for decommissioning and financial security.

There is no reliable national count of data centers already rendered economically obsolete by AI. That absence of data should not be confused with an absence of risk. The evidence instead reveals an industry facing rapid technological change, recurring capital requirements, uncertain future demand, and substantial public infrastructure exposure. Before granting tax abatements, expanding transmission capacity, or committing scarce water resources, communities should demand answers to four questions: How long will this particular facility remain economically competitive? Who pays for its upgrades? Who pays if the developer leaves? And who guarantees that the land and infrastructure will be restored if the project fails?

A server can be replaced. An aquifer cannot necessarily be restored. And a community should not be expected to underwrite the consequences of technological obsolescence while the developer keeps the upside. More importantly, the environmental consequences of building and operating that facility may substantially outlast the useful life of its equipment. This is the uncomfortable asymmetry at the center of the AI investment bubble.

The technology may become obsolete quickly. The environmental consequences may not. There is no reason to assume that the next generation of AI companies will need precisely the gigantic facilities being built today, or that the residual value of those facilities will justify the resources consumed and liabilities incurred in their construction. That would be the first time that evolving technologies got bigger rather than smaller. The fact that some entrepreneurs may eventually purchase distressed AI infrastructure at bargain prices does not establish that society received such a bargain.

The Cost to Human Creativity

Unlike the earlier infrastructure booms, generative AI is being promoted not simply as a means of increasing human productivity but also as a substitute for human work. In the music business, the distinction is especially apparent. Companies developing generative AI systems have used enormous quantities of copyrighted works in circumstances that have generated substantial disputes over authorization, compensation, and the rights of the people whose creative labor supplied the underlying material.

The industry’s investment proposition squarely depends on capturing the value of human creativity while reducing the cost of obtaining it. That introduces another kind of potentially irreversible consequence. An artist whose livelihood is displaced by a speculative technology cannot necessarily recover the lost opportunities when the company deploying it goes bankrupt. A songwriter whose works have been used without authorization does not automatically receive compensation because an AI developer’s assets are purchased by another company. And a creative profession weakened by years of uncompensated technological substitution may not spontaneously regenerate after the market corrects.

The infrastructure bubble may leave behind computing facilities. But what happens to the human infrastructure—the trained musicians, writers, performers, and other creators whose work helped make the technology possible? That question is missing from the traditional story about technological progress emerging from financial wreckage.

Everyone Forgets How Bad the Last War Really Was

Perhaps the most troubling feature of Dowd’s argument is not his economic historical premise, but the reassurance that some may draw from it. Yes, capitalism has repeatedly financed useful infrastructure through speculative excess. Yes, investors have repeatedly lost enormous amounts of money. And yes, subsequent generations have sometimes benefited from the wreckage.

But history is not an accounting exercise in which eventual benefits automatically erase earlier losses. As they say, in the long run we are all dead. The dot-com collapse was not an amusing intermission between the invention of the Internet and the arrival of AI. It was a devastating economic event for many people who had invested their money, careers, and confidence in what they were told was the future. You know, because China. I remember.

And unlike the dot-com boom, the AI infrastructure boom is reaching deeply into the physical environment, the electric grid, water resources, local government finances, and the livelihoods of people who never volunteered to participate. When the speculative capital disappears, those obligations and consequences may remain. That makes the stakes considerably higher than an investor’s return on capital. I’m going out on a limb here, but my bet is that the Sam Altman’s of this world could care less who loses money or has their lives destroyed. He clearly could care less about musicians and authors, I have no doubt about that part.

Dowd may be right that speculative bubbles are a recurring feature of capitalism. But that observation should lead us to a very different conclusion. If bubbles are a predictable feature of capitalism, then protecting the public from their predictable consequences ought to be an equally predictable feature of public policy. Which it most definitely is not. We should not wait for the crash to discover whether adequate safeguards were in place.

We should insist now on enforceable protections against stranded asset utility costs, meaningful financial assurances, responsible water use, environmental restoration obligations, and independent scrutiny of the economic claims used to justify these enormous projects. And we should stop assuming that the eventual survival of a technology necessarily vindicates the financial and political decisions made in its name.

The next generation may inherit valuable infrastructure from today’s artificial intelligence boom. It may also inherit obsolete equipment, depleted aquifers, stranded electrical assets, disrupted labor markets, and communities left to repair damage that never appeared on the investors’ balance sheets. Both outcomes are possible. Both belong in the analysis.

Those of us who lived through the dot-bomb years know that the history of a speculative boom looks very different from the other side of the crash. Everyone remembers who won the last war. Too few remember what the war cost.

The railroad tracks survived the railroad bubble. Will the aquifers survive the AI bubble? Will the musicians?

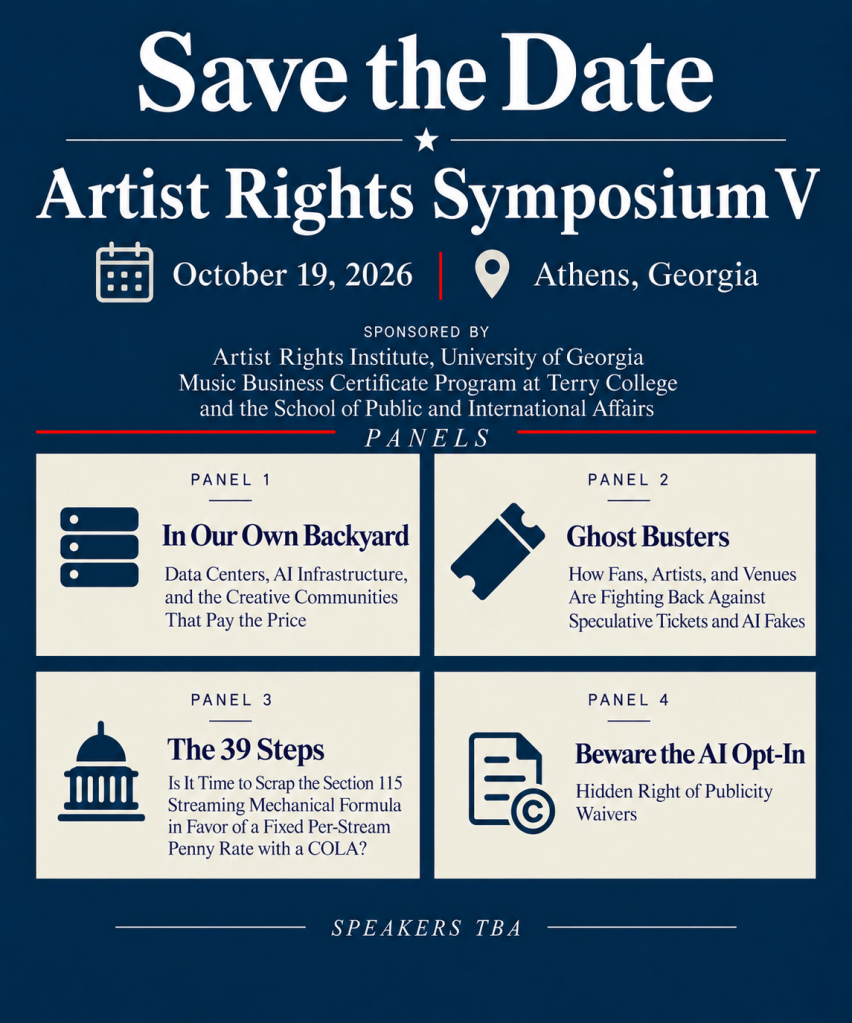
@ArtistRights Symposium 5 Panel: Beware the AI Opt-In: Hidden Right of Publicity Waivers

Registration is open for Artist Rights Symposium 5 at Eventbrite!

The Artist Rights Symposium 5 is coming on October 19 at Tweed Recording in Athens, GA hosted by the University of Georgia Terry College of Business Music Certificate Program and the School of Policy and International Affairs, and the Artist Rights Institute. More about the Symposium here and register on Eventbrite here.

As AI companies like Suno and Udio settle copyright lawsuits with record companies and music publishers, they introduce new licensing arrangements. Artists and songwriters may be offered the “opportunity” to “opt in” to the settlements and “new revenue streams”. But not all revenue streams are equal, remember streaming? Remember “Let’s help that plucky startup Spotify”? We have seen this movie before and we know how it ends.

Why a Suno Copyright Settlement Is Different from Spotify, LimeWire—or Even Bartz

The music industry has settled copyright infringement disputes before. Spotify’s mechanical royalty settlements in David Lowery’s class action resolved claims over unpaid or improperly licensed compositions. LimeWire’s settlement addressed unauthorized reproduction and distribution of copyrighted recordings. In both cases, the essential bargain concerned compensation for past copyright infringement, not permission to reproduce the identity of the human beings who created the music. Identity theft never came up.

Suno presents a fundamentally different problem. Its generative AI technology can potentially reproduce not merely copyrighted expression but recognizable characteristics of an artist’s voice, performance and identity—what Chris has called  personhood signals. A settlement that licenses recordings for future training may therefore implicate rights that neither the record company nor publisher controls. That’s why they need the “opt in” agreement to waive these rights because the AI platform doesn’t want to pay for the artist’s identify if the artist would even consider that deal. Many artists and songwriters, if not most, will not.

The Bartz v. Anthropic settlement illustrates the limitation of treating AI disputes exclusively as copyright cases. Bartzcompensates copyright owners for specified historical conduct involving pirated books. It settles the claims brought in litigation, so does not expressly resolve the separate problem of extracting and commercializing human identity. That is what a conventional copyright settlement misses.

Settling infringement of the work does not settle exploitation of the person. And no copyright settlement should quietly become consent to commercialize someone’s voice, identity or personhood.

So artists, their managers and lawyers are asking, what exactly are we being asked to agree to this time? Before you even get to the “new revenue stream,” an opt-in for an apparent copyright settlement may also include permission for future AI training, broad releases, perpetual covenants not to sue, or waivers of an artist’s rights in their name, voice and identity. These are fundamentally different transactions, with potentially permanent consequences. Before signing, creators need to understand not only what they will be paid, but what rights they are surrendering, how those rights may be exploited, and whether they can ever get them back.

Meet the Panelists

Chris Castle will lead the closing panel at Artist Rights Symposium 5, that warns “Beware the AI Opt-In: Hidden Right of Publicity Waivers.” The panel brings together four speakers with complementary perspectives on artist advocacy, litigation and music-industry licensing.

Jen Jacobsen, Artist Rights Alliance.  Friend of the show Jen Jacobsen is a long time artist rights advocate who brings the artist-advocacy perspective, focusing on meaningful consent, transparency and protecting musicians from agreements that may surrender irreversible grants of rights with hidden waivers.

George Zelcs of Korein Tillery.  George Zelcs is the lead counsel on the Jason Isbell/David Lowery personhood class action against Suno to help us understand the implications of “opt in” agreements with waivers on rights of publicity and the practical question of what remedies artists should retain.

Gwendolyn Seale — Gwen Seale PLLC.  Gwen brings experience representing songwriters and music copyright owners, with particular relevance to licensing authority, co-writer and co-owner interests, compensation and contractual protections.

Tim Kappel — Wells Kappel.  Tim is a copyright expert and artist rights advocate who successfully argued in federal trial court and the Fifth Circuit Court of Appeals that his client Cyril Vetter should retain foreign rights as part of a statutory copyright termination— a case now before the U.S. Supreme Court. 

The panel is scheduled for 3:00–4:00 p.m. on October 19. 

Three Deals Disguised as One?

An AI opt-in may combine three distinct transactions as part of the copyright settlement and go-forward license: compensation for past unauthorized uses (probably not shared by the label, but check), licensing for future model training, and revenue sharing from products built on those models (but don’t hold your breath). But accepting settlement compensation for yesterday’s conduct should not automatically mean consenting to tomorrow’s exploitation. 

There may also be a fourth transaction: authorization to use an artist’s name, voice, likeness or other personhood rights which could not have been brought by a record company or music publisher because they do not control those rights.

A copyright license is not permission to commercialize personhood.

The panel will examine how these rights can become entangled, particularly when record companies, publishers or other representatives may not control all the rights an AI company seeks.

What Happens After You Sign?

The panel will address the questions that can be overlooked when attention focuses on the size of a settlement or the promise of future royalties.

What exactly is inside the AI company’s “walled garden”? How are revenues attributed to particular recordings or compositions? Can users generate synthetic voices or prompt an artist’s name? Can artists examine the product before consenting? 

And what happens when an artist wants out later when the term expires (if there is a term)? Deleting a source recording does not necessarily remove its influence from an already-trained model. Termination, machine unlearning, continuing model exploitation and rights that survive expiration may determine whether an opt-in becomes a one-way door in an AI Hotel California.

Register for Artist Rights Symposium V on Eventbrite

Related reading: The AI “License” That Isn’t: A Musician’s Checklist for Spotting a Covenant Not to Sue Censorship Trap in Disguise.

@ArtistRights Symposium 5 Panelists: Ghost Busters: Fighting Back Against Speculative Tickets

Registration is open for Artist Rights Symposium V at Eventbrite!

The Artist Rights Symposium V is coming on October 19 at Tweed Recording in Athens, GA hosted by the University of Georgia Terry College of Business Music Certificate Program and the School of Policy and International Affairs, and the Artist Rights Institute. More about the Symposium here and register on Eventbrite here.

We’ll be posting panel overviews to introduce you to the speakers, starting with the ticketing panel. From nonexistent World Cup tickets to a growing state-by-state push for resale reform, the ticketing debate is moving quickly. “Ghost Busters: How Fans, Artists, and Venues Are Fighting Back Against Speculative Tickets” will examine what artists, venues and lawmakers can do about ghost tickets, predatory resale and a secondary market increasingly disconnected from the artists who create the event. 

The panel begins at 11:30 a.m. on October 19 at Tweed Recording with these experts: 

Randy Nichols, a board member of the National Independent Talent Organization, leads NITO research and policy efforts addressing predatory resale practices. A longtime artist manager and entrepreneur, his advocacy draws on two decades of experience in the live-music business.

Jay Gilbert, co-founder of Label Logic and co-host of Your Morning Coffee, brings decades of music-industry experience, including executive roles with Universal, Sony and Warner and marketing campaigns for artists ranging from Nirvana and The Police to Bob Marley and Johnny Cash.

Moderating is Mala Sharma, co-founder and president of Georgia Music Partners, whose career spans record labels, artist management, entertainment banking, the Atlanta Symphony Orchestra and public policy.

The conversation:  Who should control a ticket after it goes on sale—and how do we stop people from selling tickets they never owned in the first place?

UGA School of Public and International Affairs Joins Artist Rights Symposium 5

We’re pleased to announce that the University of Georgia’s School of Public and International Affairs has joined the Artist Rights Institute and UGA’s Music Business Certificate Program at Terry College as a sponsor of the fifth annual Artist Rights Symposium, October 19, 2026, in Athens, Georgia.

The addition of SPIA is especially timely. This year’s Symposium reaches beyond traditional music-industry issues to examine the broader public-policy consequences of artificial intelligence—from the massive data centers, energy infrastructure, and local communities supporting AI development to the legal and policy questions surrounding artist consent, identity, compensation, and the use of creative work.

Bringing together music business, law, public policy, artists, advocates, and policymakers is exactly what this moment requires.

Artist Rights Symposium V
October 19, 2026 — Athens, Georgia
Speakers and additional program details coming soon.

Bankruptcy Shield as a Sword: The Startup Gets Acquired Without Being Acquired

The proposed sale of Spirit Airlines’ enormous internal dataset to Google exposes a potentially dangerous new loophole in the AI economy. Google won a bankruptcy auction with a $10 million bid for Spirit’s enterprise data and says the material could help improve its products and AI models. The corpus reportedly includes approximately 100 million emails, 500 million Microsoft Teams messages, software code, operational information and decades of business records. (Reuters)

But there is a threshold question that shouldn’t get lost in the excitement over turning bankrupt companies into AI training datasets: Did Spirit actually own everything it proposed to sell? (For BK fans, Spirit’s liquidation is proceeding under Chapter 11, not Chapter 7. See In re Spirit Aviation Holdings, Inc., No. 25-11897 (SHL) (Bankr. S.D.N.Y.). As part of that proceeding, the debtors auctioned a deidentified enterprise dataset on August 14, 2026, selecting Google’s $10 million bid, although approval of the sale remains contested. Chapter 11 isn’t limited to reorganizations. It can be used for an “orderly liquidation,” with § 363 sales disposing of assets while the debtor remains in Chapter 11.)

Possession Is Not Ownership

Springshot, a technology startup whose proprietary airline-operations platform was embedded in Spirit’s technology stack for its final three years, says potentially not. Springshot has objected that the sale agreement defines the dataset so broadly that it may encompass Springshot’s own intellectual property and proprietary information. It wants the bankruptcy court to require a forensic process separating Spirit’s property from property belonging to third parties before anything goes to Google. (Ars Technica)

Springshot founder Doug Kreuzkamp states the basic principle perfectly: “The possession of IP is not ownership.” After all, a debtor’s server is a container, not a chain of title. It may hold the debtor’s property alongside licensed technology, vendor trade secrets, confidential communications, employee information and intellectual property belonging to somebody else. Bankruptcy shouldn’t improve the debtor’s title or expand the debtor’s assets just because someone else’s asset happens to be stored in the wrong place.

Bankruptcy as a Sword

That becomes particularly important with AI because bankruptcy can potentially be transformed from a shield for a distressed debtor into a sword for the purchaser when the debtor’s assets are auctioned off in liquidation. The sequence is straightforward: Startup develops technology → licenses it to customer → technology and know-how become embedded in customer’s systems → customer fails → bankruptcy estate sells its “dataset” → AI company trains on the corpus.

The bankruptcy proceeding has now done something much more consequential than liquidating the debtor’s assets. It may have created an efficient mechanism for aggregating information and transferring it to an AI company for a new use. That’s the loophole.

The Startup Gets Acquired Without Being Acquired

And that’s where this becomes an antitrust problem. Springshot has spent roughly 15 years developing technology used to improve airline operations. Ars reports that Google recently announced a five-year partnership with Ryanair involving airline operational data and Gemini Enterprise—putting Google’s AI efforts in an area where Springshot itself operates. Springshot consequently fears that its proprietary information could end up helping a vastly larger company compete with it.

Think about the alternatives. Google could develop competing technology. It could license Springshot’s technology. It could partner with Springshot. It could potentially acquire Springshot.

Or, potentially: Buy the data estate of Springshot’s bankrupt customer in a bankruptcy auction. That last possibility is profoundly different. Google doesn’t acquire the startup. It potentially acquires what the startup knows. There is no acquisition price paid to the startup. No negotiated license. And no conventional acquisition of the competitor to scrutinize.

As Springshot warns, the precedent could allow large amounts of startup IP to migrate to enormously powerful companies through bankruptcy proceedings. In other words, the startup gets acquired without being acquired. And there may be nothing they can do about it.

A Competition Loophole

That makes the bankruptcy loophole a competition loophole. Startups necessarily expose substantial information to enterprise customers. Integration requires documentation, workflows, support communications, operational data and technical knowledge.

Normally contracts, confidentiality obligations, trade-secret law and property rights establish boundaries around that information. But if those boundaries become uncertain when the customer goes bankrupt, the economics of dealing with large enterprise customers change.

A startup could survive while its customer fails—only to discover that the customer’s bankruptcy estate proposes to sell information embodying the startup’s technology to a company with virtually unlimited resources. The customer went bankrupt, so why should the startup’s competitive advantage be liquidated with it?

Procedure Becomes the Product

There is a broader procedural inversion here. Large corporate defendants have long understood that legal procedures nominally directed against them can sometimes produce valuable affirmative rights. A class action, for example, is ostensibly a device for aggregating claims against a defendant. But settlement can also aggregate something enormously valuable for the defendant: releases and finality.

The procedure itself creates economic value. AI may give bankruptcy proceedings a similar secondary function. Bankruptcy ostensibly protects the debtor and organizes an orderly disposition of its property. Or that’s the party line. But to an AI company seeking enormous quantities of authentic enterprise data, bankruptcy can provide something else: Aggregation.

Instead of negotiating separately with every employee, contractor, vendor and technology supplier whose information resides in a company’s systems, the purchaser buys one enormous “dataset” from the estate. What began as the debtor’s shield risks becoming the purchaser’s sword.

De-Identification Doesn’t Fix Title

Google says it will not receive personal information, and Spirit’s dataset is supposed to undergo de-identification. That’s important for privacy, but it doesn’t resolve ownership. Anonymization is not assignment. Removing a person’s name doesn’t transfer a vendor’s trade secrets. And de-identifying employee communications doesn’t necessarily establish that they can be repurposed for AI training. Privacy, ownership, confidentiality and authorization are separate questions.

A Caution for Startups: Treat Customer Data Like Inventory in a Warehouse

There is a useful analogy here to secured lending. A bank lending against inventory does not assume that everything physically sitting in the borrower’s warehouse belongs to the borrower. It identifies the collateral, determines what rights the borrower actually has in it, perfects its security interest, and worries about priority, proceeds, commingling and property belonging to third parties. So the Spirit case highlights the need to think about creditworthiness as a material deal point.

AI startups may want to start thinking about their data in much the same way. A customer’s servers are increasingly the digital equivalent of the warehouse. They may contain customer-owned information alongside licensed technology, vendor trade secrets, proprietary workflows, confidential communications, derived data and other material the customer merely possesses. If the customer enters bankruptcy, the danger is that all of this gets swept into a broadly defined “enterprise dataset” and auctioned as though possession established ownership. It doesn’t.

That means startups should protect themselves before a customer’s financial distress ever arises. Contracts should clearly establish ownership, permitted uses, AI-training restrictions, return and deletion obligations, and what happens upon insolvency. Proprietary information should be identifiable and segregated where practicable, with sufficient provenance to establish what belongs to whom.

There may even be circumstances where traditional secured-credit techniques deserve consideration as additional protection. But the distinction is important: Ownership is the first line of defense: “That isn’t property of the bankruptcy estate.” A security interest is the second: “If it is property of the estate, our rights have priority.”

A startup generally wants to win the first argument. Carelessly taking a security interest in property the startup claims to own could muddy that position rather than strengthen it, so Article 9 protection requires careful drafting.

The larger caution is simple: Bankruptcy courts have spent generations distinguishing what is in a debtor’s warehouse from what the debtor actually owns. AI should not erase that distinction merely by replacing the warehouse with a server. For startups whose technology becomes embedded in customers’ systems, data-title planning may now need to become as routine as IP assignments, confidentiality provisions and cybersecurity. The time to establish ownership and provenance is before the customer’s servers—and everything sitting inside them—show up in a bankruptcy auction.

The Rule Should Be Simple

AI has transformed old corporate records from storage liabilities into valuable assets. Spirit’s data sale shows just how valuable: companies are bidding millions for records of how real humans communicate, solve problems and operate businesses. That makes it essential to get the rule right now. Before a bankruptcy court asks what is this dataset worth?, it should ask: What exactly did the debtor own?

Bankruptcy can transfer the debtor’s assets. It should not manufacture AI rights the debtor never possessed. And it certainly shouldn’t become a mechanism through which a dominant AI company can acquire the accumulated knowledge of a startup without ever acquiring the startup itself.

Ars Technica’s report on the Spirit/Springshot dispute

The Data Center Completion Trap: When Insurance Risk Becomes Stranded Infrastructure

There may be another brake on the AI data-center boom that has received surprisingly little attention: insurance may become a binding constraint on financing and completion long before anyone runs out of enthusiasm for artificial intelligence.

This is not simply a question of whether underwriters will insure a $10 billion building against fire. The deeper problem is that modern hyperscale data centers are becoming extraordinarily large, expensive and interdependent infrastructure projects that struggle to maintain a semblance of a capex construction budget. A single campus can combine data halls, substations, specialized transformers and switchgear, cooling systems, fiber, batteries, transmission infrastructure and, increasingly, dedicated power generation—each component of which is a complex system with a significant overbudget risk.

Once a developer adds on-site generation, what looks like a single data-center development can effectively become two major construction projects—a data center and a power plant. That creates something much more consequential than ordinary construction risk. It creates completion risk. The movie business knows all about completion bonds, but no movie ever cost as much as a data center.

Ninety-Eight Percent Finished Can Still Mean Zero Revenue

A data center is not economically complete merely because the building is standing. It must be electrified. The cooling systems have to work. Transformers and switchgear must be installed and commissioned. Fiber must be connected. The facility must satisfy its performance requirements. And, most importantly, there must actually be enough continuous electricity available to operate it. 24/7/365.

A hypothetical $8 billion facility that is 98% physically complete but cannot obtain its final power connection isn’t necessarily worth $7.84 billion. As an operating data center—which it isn’t—it may be worth very little until somebody solves the missing 2%. It might even be worth zero.

And that is where the insurance problem gets interesting. Traditional builder’s-risk insurance generally responds to physical loss or damage. Delay-in-start-up coverage can protect against certain resulting revenue losses, but ordinarily there must first be an insured event triggering the coverage. A project delayed because a transformer was destroyed in a fire presents a familiar insurance problem.

But a project delayed because its grid connection never materializes, a transmission line project is cancelled, a regulator changes course, a federal or state political moratorium intervenes, or sufficient electricity simply isn’t available presents a very different one. This includes a data center that is planned with behind the meter nuclear power, but the nuclear plant cannot get built.

Physical damage is easy to understand. Yet, there can be catastrophic economic loss without catastrophic physical damage. That distinction could become increasingly important as the industry attempts to build larger facilities in places where electricity infrastructure is already the project’s principal constraint.

Now Add the Banks

The problem becomes considerably more interesting when viewed through the capital structure. Large infrastructure projects increasingly rely on project-level financing in which lenders ultimately expect repayment from cash flows generated by the completed facility. During construction, however, lenders typically want considerably more protection against the possibility that the asset never reaches commercial operation. We joke that the music business is the only business in the world where an asset is worth more before it’s put in service than after. Not so funny applied to data centers.

That protection can include sponsor guarantees, cost-overrun commitments, completion guarantees, debt-service support and other forms of recourse. The project’s economics therefore change dramatically depending upon whether it successfully crosses the line from construction risk to operating risk. And that creates what might be called the data-center completion trap.

Imagine an $8 billion data center. Seven billion dollars has already been spent. The buildings are substantially complete. Equipment is installed. Customers may be waiting. Then the transmission solution fails.

Walking away means potentially crystallizing an enormous loss. So spending another $500 million to solve the power problem may appear perfectly rational. Then another problem emerges. Another $750 million may still look rational compared with abandoning the original $7.5 billion. The project has entered the classic sunk-cost problem—but with a particularly dangerous infrastructure twist:

The more capital that has already been sunk into the project, the greater the economic incentive to commit additional capital to rescue it, even as the assumptions that justified the original investment deteriorate. That is the completion trap.

Going Off Grid Doesn’t Necessarily Solve It

One increasingly popular response to grid constraints is behind-the-meter generation. Can’t get enough electricity from the grid? Build your own. That’s not really an answer if you’re actually doing it. It’s right up there with “because China” as the AI rationale. That may solve one problem while creating several others.

The developer now needs not merely a functioning data center but a functioning generating plant. That can introduce fuel-supply agreements, turbines, pipelines, environmental permits, additional construction contracts, emissions requirements and entirely new categories of operating and equipment risk.

The project’s dependency chain gets longer and longer. And every additional dependency creates another possible route by which a nearly completed project can fail to reach commercial operation. Reuters recently reported that grid bottlenecks are pushing businesses toward larger on-site power systems. That trend deserves to be understood not simply as an electricity story.

It is also a risk-transfer story. The grid constraint doesn’t disappear. Some of the risk associated with solving it simply migrates onto the developer’s balance sheet.

The Insurance Capacity Feedback Loop

Now consider what happens to insurers. Insurers don’t evaluate a $10 billion hyperscale campus solely by asking whether the building is likely to catch fire. They also manage aggregate exposure. How much capital is exposed at one location? To one natural catastrophe? To one electrical system? To one equipment manufacturer? To one utility? To one geographic concentration?

Aon has warned that the enormous concentration of value in hyperscale facilities creates the possibility that a single event can produce a portfolio-level loss for insurers and reinsurers. That creates a potentially important feedback loop:

Bigger projects → larger probable maximum losses → scarcer insurance capacity → higher premiums and deductibles → lower available limits → greater retained sponsor risk → tighter lender requirements → higher cost of capital → weaker project economics.

There is something important buried in that sequence. Insurance capacity is itself capital. And unlike GPUs, transformers or gas turbines, developers cannot simply manufacture more of it. An insurer or reinsurer must be willing to put its own balance sheet behind the risk. At sufficient concentrations, the rational answer may be higher prices, lower limits, exclusions, syndication across numerous carriers—or simply no. That can ultimately produce a constraint that receives far less attention than electricity or chips: bankability.

The Bankability Cliff

Consider the conversation among the three principal sources of risk capital. The lender asks: Is completion risk adequately transferred? The insurer answers: We don’t cover all of it.

The sponsor therefore has to retain the uncovered risk. The lender responds: Then we need more sponsor support.

The sponsor recalculates its expected return. At some point, the additional equity, guarantees, contingency reserves, insurance costs and financing expenses required to make the project bankable can push the project’s risk-adjusted return below the sponsor’s required return.

Understand how weirds this is. Nothing has physically prevented construction. There may still be enormous demand for AI. The developer may still believe its long-term demand forecast. And yet the project doesn’t finance.

That is the bankability cliff.

Now Connect It to Stranded Assets

This brings us back to the larger problem surrounding the data-center infrastructure boom. A data center cancelled before construction begins may be embarrassing, but the economic damage is comparatively containable. A project that fails after billions of dollars have been spent is something else entirely. And if this starts happening at a rate that anyone can call “frequently” cold feet will break out all over.

By then there may already be substations, transmission lines, gas pipelines, generating plants, water infrastructure and roads built specifically to accommodate the expected load. There may also be something much harder to reverse: eminent domain.

Property may have been condemned and permanent transmission easements imposed on landowners because planners concluded that enormous future electrical loads required new infrastructure. What happens if the private project that justified that infrastructure never reaches commercial operation? The developer takes a loss—although loss doesn’t quite cover it. The lender restructures the debt. Investors write down their equity.

But the landowner doesn’t get their family ranch back. And the transmission corridor doesn’t magically disappear.

Completion Risk Is Therefore a Public-Policy Question

This suggests that regulators may be asking the wrong question when evaluating enormous new data-center loads.

It isn’t enough to ask: Does the developer have financing? Nor is it enough to ask: Has somebody agreed to build the data center?

The better question is:

Has the developer demonstrated sufficient committed capital, insurance, power supply, equipment availability, completion guarantees and contingency resources to reach commercial operation if the original construction and power plan fails?

That is a much tougher test. And if data centers become poster children for bad investments…lenders will want out.

Before approving billions of dollars of transmission investment—or allowing eminent domain to be exercised on the assumption that a 1-gigawatt data center will exist—regulators might reasonably demand evidence that the project is not merely financeable enough to start. It needs to be financeable enough to finish.

The Risk Nobody Is Pricing Correctly

Much of the debate over stranded AI infrastructure assumes a particular sequence: AI boom → enormous data-center construction → AI bubble bursts → completed facilities become stranded assets.

There is another possibility. Some projects may never reach the third step. The constraint may arrive during construction, when increasingly enormous and interconnected projects encounter an insurance market unwilling to absorb all of their risk, lenders unwilling to accept what remains, and sponsors unwilling or unable to provide unlimited completion support.

The resulting stranded asset would not be an obsolete data center.

It could be a half-completed infrastructure ecosystem. And some portion of that abandoned ecosystem—transmission lines, substations, generating plants, pipelines and condemned rights-of-way—may already have been imposed on communities because somebody’s spreadsheet said the projected load was coming. Or because China.

That is why insurance belongs in the data-center backlash discussion. Insurance risk becomes completion risk. Completion risk becomes credit risk. Credit risk becomes stranded-asset risk. And when public infrastructure and eminent domain have already been committed to the project, private completion risk can become public risk.

The most dangerous data-center forecast may therefore not be the one predicting how much electricity artificial intelligence will consume in 2035. It may be the assumption hidden underneath it: that every project we are building the infrastructure for today will actually make it to the finish line.

That assumption must be phrased as a question: Will this project get finished on time and at least somewhat on budget.

Good luck with that.

A Tale of Two AIs: Wall Street, Main Street, and Taking the Theft Out of Artificial Intelligence

There are increasingly two conversations about artificial intelligence in America, and they are beginning to collide. These are familiar opponents: Wall Street and Main Street.

Pressure from Financial Markets

The first is taking place on Wall Street.

For publicly traded companies that aggregate, distribute, and monetize enormous quantities of creative content, being seen as an AI skeptic is increasingly difficult. Investors expect an AI strategy. Analysts ask about AI on earnings calls. Companies announce AI partnerships (which can get pompous like “global strategic partnerships” and are neither), a few AI licensing arrangements, claimed AI efficiencies, AI products and AI revenue opportunities. Emphasis on the opportunities in the search for elusive ROI.  Warner Music Group, for example, recently told its shareholders that it has taken an “early and aggressive approach” to AI partnerships and emphasized the variable economics of its deals with Suno and other AI companies. Universal Music Group likewise regularly highlights its growing portfolio of “responsible AI” partnerships in financial reporting.

That should hardly be surprising. AI has become deeply embedded in the capital markets themselves.

The largest technology companies are spending extraordinary sums on AI infrastructure. Chipmakers like NVIDIA finance customers who buy their chips. Reminiscent of circular “carriage deals” in the Dot Bomb era, technology companies invest in AI companies that become customers of their cloud services. Infrastructure companies borrow against anticipated demand from AI companies, while investors value many of the participants based partly upon the growth generated by the others.  See how that works?

The circularity is becoming difficult to miss. NVIDIA, for example, recently agreed to provide guarantees of up to $105 billion supporting an OpenAI data-center project in Ohio while also investing in OpenAI. Broadcom reportedly is exploring tens of billions of dollars of additional financing tied to AI infrastructure. AI is no longer simply another technology sector. It increasingly influences equity valuations, credit markets, underwriting decisions, infrastructure finance and the allocation of enormous pools of investment capital.

Wall Street consequently has a powerful incentive to believe that the AI buildout will continue.  Because the emperor has new clothes, but is the same old emperor.

Data Center Backlash on Main Street

Then there is Main Street.

Main Street’s experience with AI can look remarkably different.

Musicians and songwriters discover that recordings containing their performances and songs have been copied into training datasets without permission or legal basis. Songwriters discover that their compositions, especially lyrics, may have become inputs to systems capable of producing substitutes for their work. Performers discover that their names, voices and identifying characteristics may have become instructions capable of invoking their identities inside commercial products.  Their property is being taken—there’s that word again—in a massive theft that should involve prison time.  Because if this isn’t criminal copyright infringement, what is?

Drive a few hundred miles away from Nashville or Los Angeles and the property being taken changes, but the complaint sounds remarkably similar.

A farmer is told that a transmission corridor may cross land her family has owned for generations, backed by eminent domain that can force the family to surrender it. A rural community discovers that hundreds or thousands of acres have been assembled for a data center. Residents worry about aquifers, electricity prices, noise, gas generation and transmission lines. Governments offer tax incentives to enormously valuable technology companies while residents are told that the infrastructure is necessary because America must beat China in the AI race.  State and local elected officials make zoning decisions to permit these takings, with votes that only make sense if there’s a quid pro quo under the table.

The common denominator between musicians and farmers isn’t artificial intelligence.

It is consent and coercion.  It’s the callous taking.

But there is a deeper connection. The institutions demanding these resources did not suddenly become powerful with the invention of generative AI. Much of today’s platform economy accumulated extraordinary wealth and political influence during the preceding two decades through business models built around aggregation, scale, data collection and extraordinarily aggressive interpretations of legal safe harbors. Companies such as Meta and Google learned that once a platform becomes sufficiently large, the lives, work, attention, emails, chats, and baby pictures of its users can become inputs to be captured, scraped, optimized, aggregated and monetized.

The ongoing multidistrict litigation over social-media harms (MDL 3047) provides a sobering illustration of where that philosophy can lead. The allegations in the social media harms cases concern platforms accused of designing products to maximize engagement while exposing their own users—including children—to serious harms and exploiting those harms.  Cold blooded. Whatever the ultimate disposition of those cases in MDL 3047, they illustrate a recurring tension in the platform economy: the interests of the human beings using a platform and the protections they enjoy under the law and human rights are routinely trampled by the companies operating it—for the money.  And let’s not forget that when we say “companies” we actually mean the employees who went along with it and got rich doing so.

Generative AI extends that tension from users to inputs.

The same appetite for scale that drove platforms to accumulate and exploit behavioral data now creates an appetite for enormous quantities of creative work, human expression, electricity, water, land and transmission capacity. Scraping supplies one set of inputs. Political influence and infrastructure policy can supply another. And in the most extreme case, the sovereign power of eminent domain delegated to the MDL defendants can ultimately compel a property owner to surrender land for data centers serving the buildout.  If not stopped, this will give Silicon Valley a political control at the federal, state and local levels never seen before.

The mechanisms are legally different. The instinct is strikingly familiar.

Acquire the input first. Argue about permission, compensation and consequences later.  They’re happy to get a license when each artist and songwriter, or mom and child gets a final, non-appealable judgement if the AI companies don’t change the law as they tried and keep trying to do with federal preemption.

That is why the emerging alliance between musicians and landowners is less strange than it initially appears. Both increasingly confront institutions whose enormous financial resources can be converted into political and legal power, and whose growth depends upon obtaining resources belonging to other people.

For the musician, it may be a composition, performance, voice or identity. For the farmer, it may literally be the family farm. And increasingly, it is the perception that enormously powerful companies are building wealth and control over the economy by taking private property and humanity from people who possess considerably less economic and political power.

That is why dismissing the data-center backlash as NIMBYism—or dismissing musicians objecting to unauthorized training as Luddites—fundamentally misunderstands what is happening.

These constituencies are not necessarily anti-technology. They are objecting to a particular economic bargain.

Or, more accurately, the absence of one.

The Politics Are Arriving

This distinction matters because the data-center fight is rapidly escaping zoning commissions and utility proceedings and entering national politics.  This is called “jumping the shark” in some circles.

In Ohio, Sherrod Brown has already run television advertising attacking Senator Jon Husted as the “face of data centers in Ohio.” The National Republican Senatorial Committee reportedly warned AI companies privately that data-center opposition could cost Republicans the Ohio Senate seat and described the issue as a potential problem for the entire election cycle.

Texas Democrats are campaigning on data centers in rural Republican territory. Candidates elsewhere are attacking electricity costs, water consumption, tax subsidies and the conversion of agricultural land.

This is an unusual political coalition because it doesn’t fit comfortably on the traditional left-right axis.

The rancher who doesn’t want a transmission line across his property may be a lifelong Republican. The songwriter who doesn’t want her catalog ingested into a generative model may be a lifelong Democrat. The homeowners who don’t want a 500-megawatt industrial complex next door may have no particular view about AI whatsoever but want to protect their family.

They nevertheless understand the same sentence:

You shouldn’t be able to take something that belongs to me merely because you say your technology needs it.

That may prove considerably more powerful politically than “AI safety.”

What If Data Centers Become Obsolete Stranded Assets?

There is another reason the industry’s present approach seems unnecessarily confrontational and coercive.

Today’s enormous data-center buildout reflects today’s technological architecture. There is no reason to assume that every aspect of that architecture will remain necessary and may become unnecessary before the data center build is completed.

Indeed, NVIDIA—the company most closely associated with the hardware powering hyperscale AI—is simultaneously pushing substantial AI computation in the opposite direction. Its DGX Spark puts powerful model inference, fine-tuning, and autonomous-agent capabilities on a desktop, while its RTX platforms increasingly allow sophisticated AI models and agents to run locally. NVIDIA expressly markets these systems as “reducing the need for cloud-based token generation resources” and, in the case of its AI workstations, as a means to “offload data center compute resources.” This does not eliminate the need for hyperscale facilities, particularly for frontier-model training, but it demonstrates that an increasing share of AI computation can migrate from centralized data centers to local devices.

It’s a trend away from depending on data centers.  And if the answer was, you can’t build a gazillion data centers that inevitably will become stranded assets rather than  take whatever you want, do you think that trend might accelerate?  Constraints are choices.

That does not mean hyperscale data centers are disappearing. Training frontier models and serving enormous numbers of users will continue to require substantial centralized computing resources for a while.

But the direction of travel matters.

Models are becoming smaller and more efficient. Quantization reduces computational requirements. Specialized chips improve inference efficiency. More processing is moving to PCs, workstations, phones, vehicles and edge devices. Some workloads that required a data center yesterday can run locally today; workloads requiring a data center today may run locally tomorrow.

That makes the industry’s political strategy particularly shortsighted.

Why permanently alienate communities, seize land, subsidize massive infrastructure and create a nationwide political opposition movement around an architecture that technology itself is already beginning to decentralize?

True innovation would try to solve that problem if tech companies were constrained.

Take the Theft Out of AI

The same principle applies to music. The answer is not to stop artificial intelligence. The answer is to take the theft out of it.

And that requires acknowledging an uncomfortable fact about the technology as it exists today. Artificial intelligence can theoretically be useful and productive, but the major generative models did not emerge from a pristine laboratory. To one degree or another, the present generation of large models is shadowed by unresolved allegations and litigation concerning massive-scale copyright infringement, unauthorized scraping, collection of personal information and other privacy violations. Courts will ultimately decide many of those claims in their own inefficient way that Big Tech loves so much. But it is impossible to have an intellectually serious conversation about “responsible AI” while pretending that the provenance of today’s models is not itself contaminated.

That history matters because the question is not simply how AI should behave tomorrow. It is also what was taken to build the systems we have today, from whom, and without whose permission.

Just like I never believed that the law would permit “sharing” with 60 million of your closest friends in the Grokster case, I don’t believe that the AI cases will determine that the answer is because an enormously expensive technology has already been built, obtaining consent will be disregarded. (The subtext being, and if it is, we have much bigger problems.)

This isn’t that hard, people. Build models from licensed material. Ask musicians before converting their identities into commercial capabilities. Compensate creators whose work supplies valuable inputs. Give communities meaningful authority over infrastructure imposed upon them. Pay the actual cost of electricity and transmission rather than shifting it onto ratepayers. Don’t hoard power behind the meter while creating massive noise pollution and other negative externalities. Build smaller and more efficient systems.

And where existing models were built from material that should not have been taken in the first place, genuine innovators should be investing just as aggressively in provenance, licensed replacement datasets, machine unlearning and other technologies capable of removing unauthorized inputs as they invest in acquiring more compute.

That would be innovation directed at the problem rather than lobbying directed at avoiding it. Most importantly, stop treating consent as an obstacle to innovation.

The Human Artistry Campaign and Warner Music Group’s own public AI principles point toward the distinction. WMG says AI models should be licensed and that artists and songwriters should have an opt-in before their names, images, likenesses or voices are used in new AI-generated music. That is not anti-AI. It is an attempt to establish the terms under which AI can coexist with human creators. (That’s also not what happened with Suno, which is why Universal and Sony are still suing Suno.)

There is an enormous difference between saying “don’t build it” and saying “don’t build it with things you had no right to take.” Wall Street may not fully appreciate that distinction yet because markets presently reward companies for demonstrating exposure to AI growth—said another way, Wall Street rewards AI companies that take private property.

Main Street understands it instinctively.

A singer’s voice. A songwriter’s composition. A session player’s musical identity. A rancher’s land. A town’s water supply. A family’s electric bill.

They are very different things. But the political argument increasingly surrounding them is remarkably similar:

Innovation does not create an entitlement to somebody else’s property.

AI can be useful. But usefulness does not cleanse provenance, technological achievement does not retroactively supply consent, and scale does not convert unauthorized taking into a legitimate business model rather than a litigious model.

Local AI may eventually make some of today’s massive infrastructure unnecessary. Properly licensed models can create new markets for artists rather than simply competing against them. Assistive AI can make human creators more productive without replacing them.

The choice therefore isn’t between AI and no AI. It is between an AI economy built by consent and one built by extraction.

The companies that recognize that distinction first may ultimately be the genuine innovators. They will stop asking how much they can take before somebody stops them and start asking how to build technology people actually want to live with.

That is how AI earns a social contract. Take the theft out of AI, and a remarkable amount of the opposition may disappear with it.

The AI Capex Party May Be Nearing Last Call

For the past two years, Wall Street has treated artificial intelligence as a one-way trade. Hyperscalers, semiconductor companies, utilities, private-credit funds, and data-center developers have committed hundreds of billions of dollars to what may ultimately become nearly $1 trillion in AI-related infrastructure investment over roughly two years.

The underlying assumption has been remarkably consistent: demand for increasingly powerful AI models will continue growing fast enough to justify unprecedented spending on chips, data centers, transmission lines, substations, and electric generation.

But investment booms rarely end because one assumption proves wrong. They end when several assumptions begin to weaken at the same time.

That appears to be happening.

Ed Dowd’s recent Substack analysis argues that the economics supporting today’s AI buildout are becoming increasingly fragile. Financing is tightening. Enterprise customers are demanding clearer returns on investment. Open-weight models continue improving while driving prices lower. And perhaps most importantly, the physical infrastructure required to support AI is becoming a political issue.

Gary Marcus recently challenged David Sacks’ argument that regulation is the principal threat to American AI leadership (Sacks really needs some new sheet music). Marcus instead argued that the industry faces a far more fundamental economic problem:

“The real issue is that LLMs are commodities; lots of people know how to make them, and everybody is doing more or less the same thing, training on more or less the same data. That means nobody has a technical moat. Which means you get price wars and low margins and more and more competitors over time.”

If Marcus is right, Wall Street may eventually discover that AI resembles cloud computing more than pharmaceuticals. There may be tremendous demand—but not necessarily extraordinary profits. That observation dovetails with Goldman Sachs’ increasingly cautious assessment of the AI investment cycle. Goldman has repeatedly warned investors that the buildout depends on continued access to capital, sustained enterprise demand, adequate electric power, and enough economically valuable use cases to justify unprecedented capital expenditures.

AI does not exist in ‘the cloud.’ It exists on electric grids. Every new model depends on substations, transmission lines, transformers, cooling systems, water supplies, and local political consent.

For months, we’ve tracked what has become a genuine data center backlash. Communities across Texas, Georgia, Louisiana, Virginia, Oklahoma, Utah, Alabama, and elsewhere are increasingly questioning the costs of hosting massive AI infrastructure.

Politicians, meanwhile, are discovering that AI infrastructure is much easier to announce than it is to build. Many governors and local officials have promoted data centers by assuring taxpayers that the projects will ‘pay their own way.’ But that message begins to unravel the moment the infrastructure breaks ground or annexes farmland.

A homeowner facing a 765-kV transmission line across family property is unlikely to be persuaded that the project is privately financed. Likewise, a rancher confronting eminent domain does not care whether the transmission costs appear on a utility bill, a corporate balance sheet, or a tax-abatement agreement. The injury is the same: the family home, ranch, or farm is permanently altered to support infrastructure serving distant customers—who are often anonymous.

In the Texas Hill Country, landowners have mobilized against new transmission corridors intended to serve future electric demand, including AI-related growth. In Coweta County, Georgia, residents organized after learning that transmission infrastructure associated with large-scale data-center development could cut through long-held family properties. The debate quickly ceased being about economics and became about land, community, and the limits of eminent domain.

This is where many elected officials have found themselves trying to have it both ways. They assure taxpayers that private investment will shoulder the costs while simultaneously offering substantial tax abatements, infrastructure incentives, expedited permitting, and other forms of public support. Then, when opposition emerges, they discover that the political issue is no longer who pays for the infrastructure—it’s who lives with it.

For families whose property lies in the path of a transmission corridor, ‘the data centers will pay for themselves’ is not an answer. Their concern is not the financing model. Their concern is keeping the home that has been in the family for generations.

None of this means AI is a passing fad. Transformative technologies often survive speculative bubbles. The internet certainly did. But many companies that financed the dot-com boom did not survive intact, and many investors paid dearly for assuming that technological transformation automatically translated into sustainable profits.

Today’s AI investment cycle rests on multiple pillars: inexpensive capital, robust enterprise demand, premium pricing, abundant electricity, and political support for rapid infrastructure expansion. Gary Marcus questions the durability of the competitive moat. Goldman Sachs questions whether the economics can support the investment. Communities across America are questioning whether they should bear the physical burdens.

Those three conversations are converging. The story is no longer simply about faster models or larger training runs. It is about economics, infrastructure, and public acceptance. The market has spent the last two years pricing AI as though all three will remain aligned indefinitely. History suggests that is a very demanding assumption.